Quantitative research produces data in the form of numbers: survey ratings, test scores, income, age, experimental measurements, sales figures, attendance records, response times, and many other measurable variables. But collecting numerical data is only the beginning. The real research work starts when you need to determine what those numbers mean.
Quantitative data analysis is the process of organizing, exploring, summarizing, testing, and interpreting numerical data to answer a research question. Depending on the study, researchers may use descriptive statistics, correlation, regression, t-tests, ANOVA, chi-square tests, or other statistical techniques.
The challenge is knowing which method to use and when.
A researcher analyzing 500 survey responses does not necessarily need the same statistical procedure as a researcher comparing two experimental groups. Likewise, a study examining whether two variables are related requires a different approach from one trying to predict an outcome.
This guide explains how to analyze quantitative data from the initial research question through data preparation, descriptive analysis, statistical testing, interpretation, visualization, and reporting.
What Is Quantitative Data Analysis?
Quantitative data analysis is the systematic examination of numerical information using statistical and mathematical methods.
Researchers use it to answer questions such as:
- What is typical in the dataset?
- How are responses distributed?
- Are two groups different?
- Are two variables related?
- Does one variable predict another?
- Is an observed difference statistically meaningful?
- How large is an observed effect?
- Can a finding from a sample provide evidence about a wider population?
The analysis normally begins with understanding the dataset and ends with interpreting the results in relation to the original research question.
A useful way to think about the process is:
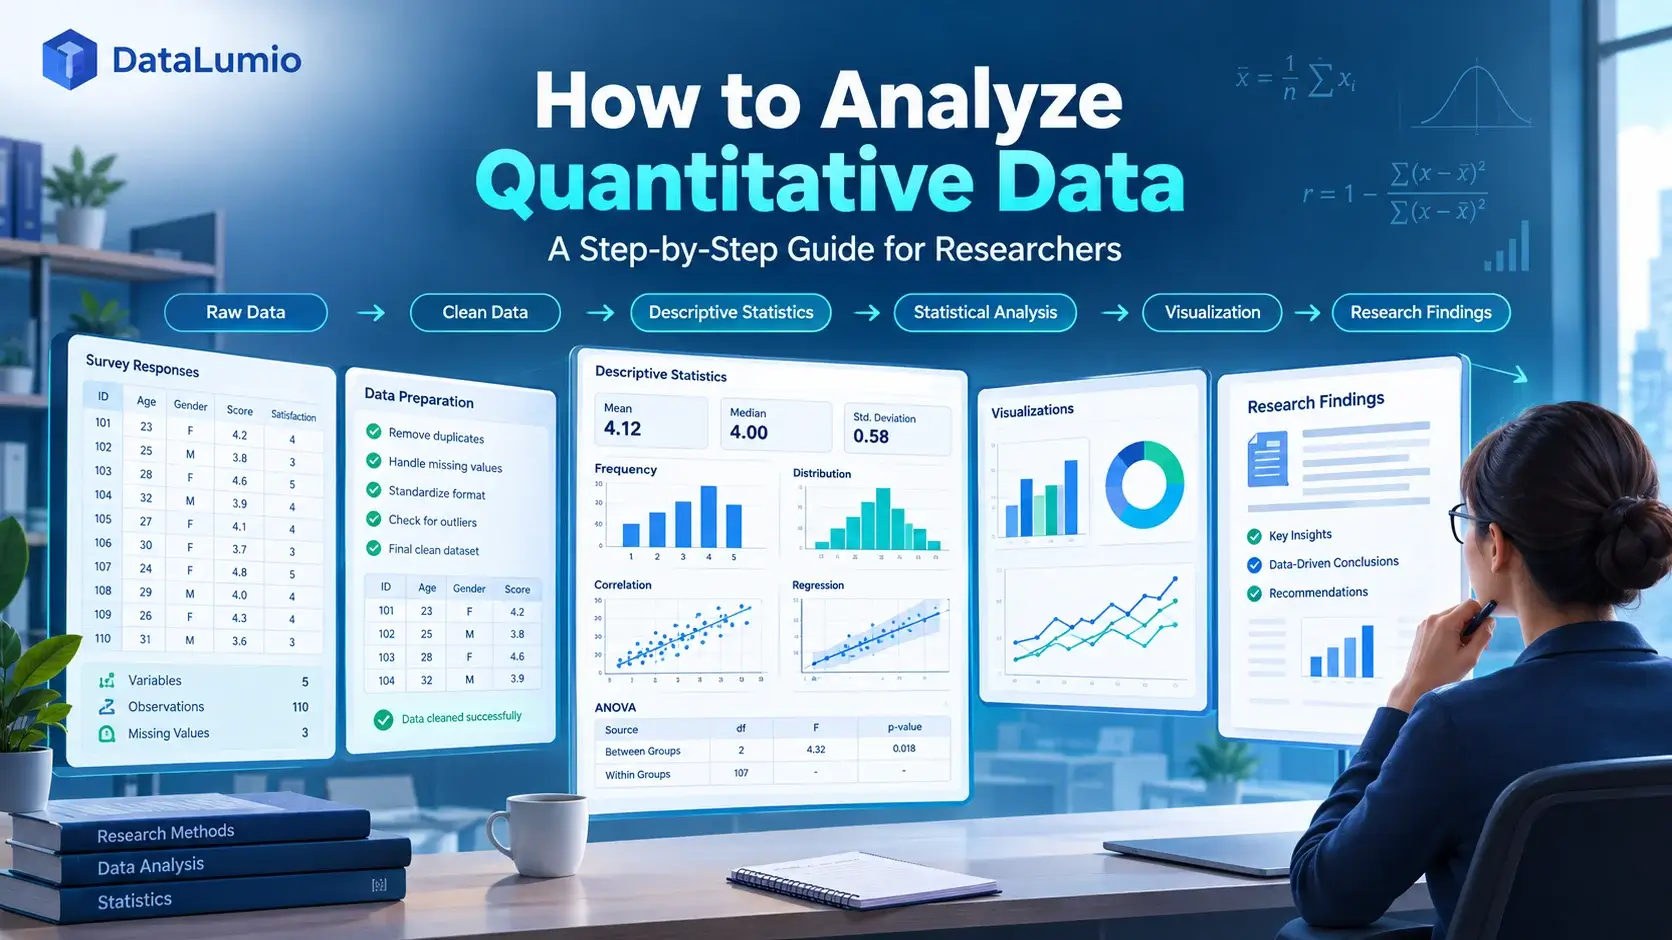
Research question → Variables → Data preparation → Exploration → Descriptive analysis → Statistical testing → Interpretation → Reporting
Quantitative research data analysis therefore involves much more than entering numbers into statistical software. The researcher must decide which variables matter, whether the data is suitable for a particular method, which assumptions need to be checked, and what the results actually mean.
What Is Quantitative Data?
Quantitative data represents measurable quantities that can be expressed numerically.
For example:
- A student’s age: 21 years
- A test score: 84%
- Monthly income: $2,500
- Study time: 12 hours per week
- Customer satisfaction: 4 out of 5
- Number of absences: 6
- Response time: 2.8 seconds
Some quantitative datasets also contain categorical variables alongside numerical variables. For example, a student survey might contain age and GPA as numerical variables while also recording gender, department, or study program as categories.
Understanding these differences is important because the type and structure of your variables influence which quantitative data analysis methods are appropriate.
Examples of Quantitative Data
Researchers encounter quantitative data across almost every field.
Education
Examples include:
- Exam scores
- GPA
- Attendance percentage
- Study hours
- Number of completed assignments
- Course ratings
Business
Examples include:
- Revenue
- Sales volume
- Customer spending
- Conversion rate
- Number of purchases
- Customer lifetime value
Healthcare
Examples include:
- Blood pressure
- Heart rate
- Age
- Weight
- Recovery time
- Dosage
Social Sciences
Examples include:
- Survey ratings
- Household income
- Age
- Number of children
- Employment status
- Questionnaire scores
Experimental Research
Examples include:
- Treatment measurements
- Reaction time
- Temperature
- Concentration
- Performance scores
- Before-and-after measurements
These are all examples of quantitative data because they can be represented numerically and analyzed using appropriate statistical techniques.
Quantitative Data vs. Qualitative Data
Both Quantitative and qualitative research answer different types of questions.
A Quantitative data is primarily numerical and is commonly analyzed with statistical techniques. Qualitative data consists of information such as interview transcripts, observations, open-ended responses, and documents and is usually analyzed through coding, categorization, and thematic interpretation.
For example:
Quantitative question:
“How many students reported studying more than 10 hours per week?”
Qualitative question:
“Why do students find it difficult to maintain regular study habits?”
A mixed-methods study can use both. A researcher might analyze numerical survey responses quantitatively and open-ended responses qualitatively to understand both the measurable pattern and the reasons behind it.
How Do You Analyze Quantitative Data?
The exact procedure depends on the research design, but a practical workflow looks like this:
- Define the research question.
- Identify the variables.
- Determine how each variable is measured.
- Prepare and clean the dataset.
- Explore the data.
- Calculate descriptive statistics.
- Choose appropriate quantitative analysis methods.
- Check statistical assumptions.
- Perform inferential analysis where appropriate.
- Interpret the findings.
- Visualize important results.
- Report the analysis clearly.
The most important principle is that the research question should drive the analysis method.
Do not begin by asking, “Which statistical test can I run?”
Start with:
“What am I trying to find out?”
Once that is clear, identify the variables involved and then select an analysis method that matches the question, data structure, and research design.
Step 1: Start With Your Research Question and Hypotheses
Before analyzing quantitative data, clearly define what the study is trying to answer.
Suppose a researcher wants to study university students’ academic performance.
A broad question might be:
“What factors are associated with students’ academic performance?”
This can be converted into more specific questions:
- Is study time related to exam scores?
- Do students who attend more classes achieve higher scores?
- Do exam scores differ between two teaching approaches?
- Can attendance and study time predict exam performance?
Each question could require a different analysis.
Identify Your Variables
A variable is a characteristic that can take different values across observations.
Common roles include:
- Independent variable: a factor that may explain or influence an outcome
- Dependent variable: the outcome being studied
- Predictor variable: a variable used to predict another variable
- Control variable: a variable accounted for to reduce confounding
For example:
Research question: Does study time predict exam performance?
- Study hours = predictor
- Exam score = outcome
If you want to examine several predictors, such as study hours, attendance, and previous GPA, a regression model may be appropriate depending on the study design and assumptions.
Define Your Hypotheses
A quantitative study may establish a null and alternative hypothesis.
For example:
Null hypothesis (H₀): Study time is not associated with exam performance.
Alternative hypothesis (H₁): Study time is associated with exam performance.
The analysis then provides statistical evidence that can be evaluated against these hypotheses.
Step 2: Understand Your Variables and Data Types
One of the most common mistakes in quantitative analysis is choosing a statistical procedure without first understanding the variables.
Categorical Variables
Categorical variables place observations into groups.
Examples include:
- Department
- Region
- Treatment group
- Education category
- Customer type
They may be nominal or ordinal.
Numerical Variables
Numerical variables represent measurable quantities.
Examples include:
- Age
- Income
- Height
- Weight
- Score
- Revenue
- Response time
Ordinal Variables
Ordinal variables have a meaningful order, but the distance between categories may not be equal.
A typical example is a Likert-scale response:
- Strongly disagree
- Disagree
- Neutral
- Agree
- Strongly agree
The way ordinal data is treated depends on the research design, measurement properties, and statistical method.
Measurement Scales
Researchers commonly distinguish between:
- Nominal
- Ordinal
- Interval
- Ratio
Knowing the measurement level helps determine which quantitative analytical methods are suitable.
Step 3: Prepare and Clean Your Quantitative Data
Good statistical analysis starts with good data.
Before calculating statistics, inspect the dataset for problems that could distort the findings.
Check for Missing Data
Look for:
- Empty cells
- Missing survey responses
- Unavailable measurements
- Incomplete records
Do not automatically replace every missing value with zero.
Zero may represent a real measurement, whereas a blank value may mean the information was never recorded.
First determine why the data is missing and then select an appropriate treatment based on the study design and analysis.
Check for Duplicate Records
Duplicate observations can change frequencies, averages, and statistical results.
For survey research, for example, determine whether repeated records represent legitimate repeated responses or accidental duplication.
Check Data Types
Make sure numerical variables are actually stored and interpreted as numbers.
For example:
25
and
"25"
may look identical to a human but can behave differently in a dataset.
Also check:
- Units
- Decimal places
- Category coding
- Date formats
- Reversed questionnaire items
Identify Outliers
An outlier is an observation that is unusually different from the rest of the dataset.
An unusual value should not automatically be deleted.
First ask:
- Is it a data-entry error?
- Is it a genuine observation?
- Is it caused by a measurement problem?
- Does the research design provide a reason to exclude it?
- Does it substantially influence the selected analysis?
Outlier handling should be documented rather than performed silently.
Step 4: Explore the Dataset Before Statistical Testing
Exploratory analysis helps you understand what your data actually looks like before you choose a formal statistical test.
Start with:
- Frequencies
- Percentages
- Distributions
- Minimum and maximum values
- Histograms
- Box plots
- Scatter plots
- Cross-tabulations
Suppose a researcher calculates the average income of a sample and obtains a surprisingly high mean.
A distribution plot may reveal that most observations are clustered at lower values while a small number of very high incomes are pulling the mean upward.
That information can influence how the researcher describes the dataset and which statistical methods are appropriate.
Exploration is therefore not an optional decoration before “real” analysis. It is part of understanding the data.
Step 5: Perform Descriptive Quantitative Data Analysis
Descriptive analysis summarizes the data you collected.
It does not, by itself, establish that a relationship or difference exists in a wider population.
Common descriptive measures include:
Mean
The arithmetic average.
For example, if five students score:
70, 75, 80, 85, 90
the mean is:
80
Median
The middle value after observations are ordered.
The median can be particularly useful when a dataset is skewed or contains extreme observations.
Mode
The most frequently occurring value or category.
Range
The difference between the maximum and minimum values.
Variance
A measure of how much observations vary around the mean.
Standard Deviation
Standard deviation describes the spread of observations around the mean.
A small standard deviation indicates that observations tend to be relatively close to the mean, while a larger value indicates greater dispersion.
Frequencies and Percentages
These are particularly useful for categorical variables.
For example:
| Response | Frequency | Percentage |
|---|---|---|
| Strongly disagree | 20 | 8% |
| Disagree | 35 | 14% |
| Neutral | 50 | 20% |
| Agree | 90 | 36% |
| Strongly agree | 55 | 22% |
Together, these statistics provide a first description of the dataset.
Step 6: Choose the Right Quantitative Data Analysis Method
Choosing the right method is one of the most important parts of data analysis in quantitative research.
There is no single statistical test that works for every dataset.
The choice depends on:
- Research question
- Study design
- Variable types
- Number of groups
- Sample characteristics
- Distribution
- Statistical assumptions
- Whether you are describing, comparing, associating, or predicting
Here are some common quantitative analysis methods.
Descriptive Analysis
Use descriptive analysis when your objective is to summarize the data.
Common techniques include:
- Mean
- Median
- Mode
- Standard deviation
- Variance
- Frequency
- Percentage
- Range
- Quartiles
Example
A researcher wants to describe the average GPA and distribution of GPA among 500 students.
Descriptive statistics would be an appropriate starting point.
Comparative Analysis
Comparative methods are used when researchers want to determine whether groups differ.
Independent-Samples t-Test
An independent t-test can be used in appropriate circumstances to compare the means of two independent groups.
Example:
Do students who use Teaching Method A have different average test scores from students who use Teaching Method B?
Paired-Samples t-Test
A paired t-test can be used for appropriate paired observations.
Example:
Did students’ test scores change after an intervention?
The same participants may be measured before and after the intervention.
ANOVA
Analysis of variance, or ANOVA, is commonly used when comparing means across three or more groups.
Example:
Do average satisfaction scores differ across three university departments?
A significant overall ANOVA result indicates that the group means are not all equal, but additional analysis may be needed to determine which groups differ.
Correlation Analysis
Correlation measures the strength and direction of association between variables.
For example:
Is study time associated with exam performance?
A positive correlation indicates that higher values of one variable tend to occur with higher values of another.
A negative correlation indicates that higher values of one variable tend to occur with lower values of another.
A correlation near zero indicates little linear association.
However, correlation does not establish causation.
If students who sleep more also achieve higher scores, the relationship does not automatically mean that increased sleep caused the higher scores. Other factors may contribute to both variables.
Depending on the data and assumptions, researchers may consider methods such as Pearson or Spearman correlation.
Regression Analysis
Regression is used to examine relationships between variables and, in suitable circumstances, model or predict an outcome.
For example:
Can study hours, attendance, and previous GPA predict final exam scores?
A multiple regression model might include:
- Study hours
- Attendance
- Previous GPA
as predictors and:
- Final exam score
as the outcome.
Researchers should examine the model’s assumptions, coefficients, fit, uncertainty, and substantive meaning rather than relying on a single output value.
Chi-Square Analysis
Chi-square tests are commonly used when examining relationships involving categorical variables.
For example:
Is student satisfaction category associated with academic department?
The researcher might create a contingency table containing:
- Department
- Satisfaction category
A chi-square analysis can then be considered when the data and assumptions meet the requirements of the test.
Nonparametric Quantitative Analysis Methods
Parametric tests are not always appropriate.
Depending on the data and research question, researchers may consider nonparametric methods such as:
- Mann–Whitney U
- Wilcoxon signed-rank
- Kruskal–Wallis
- Spearman correlation
These methods can be useful for certain ordinal, non-normal, or otherwise unsuitable datasets.
The decision should be based on the properties of the data and the assumptions of the method rather than simply choosing a test because it is easier to run.
Types of Quantitative Analysis
The phrase types of quantitative analysis can refer to different ways of classifying statistical work.
The most useful categories for researchers are:
Descriptive Quantitative Analysis
Answers:
What does the dataset look like?
It includes frequencies, averages, measures of spread, and distributions.
Inferential Quantitative Analysis
Answers questions about relationships, differences, or effects and uses sample data to make statistical inferences.
Comparative Analysis
Answers:
Are groups or conditions different?
Examples include t-tests and ANOVA.
Correlational Analysis
Answers:
Are variables associated?
Examples include Pearson and Spearman correlation.
Predictive Analysis
Answers:
Can one or more variables help predict an outcome?
Regression is a common example.
Exploratory Analysis
Exploratory analysis examines patterns, distributions, unusual observations, and potential relationships before or alongside formal testing.
These categories can overlap. A single research project may use several types of analysis.
Step 7: Check Statistical Assumptions
Choosing a test is not enough.
Many statistical procedures have assumptions that should be evaluated before interpreting their results.
Depending on the analysis, these may include:
Normality
Some statistical methods rely on assumptions about the distribution of data or residuals.
Independence
Observations should meet the independence requirements of the selected analysis.
Homogeneity of Variance
Some comparisons assume that groups have sufficiently similar variance.
Linearity
Correlation and regression analyses may require relationships to meet particular linearity assumptions.
Multicollinearity
When several predictors are included in a regression model, strong relationships among predictors can complicate interpretation.
Sample Size
Sample size influences statistical power, precision, and the reliability of estimates.
The exact assumptions depend on the statistical procedure. Researchers should therefore check the requirements of the method they intend to use rather than applying one generic checklist to every analysis.
Step 8: Perform Inferential Data Analysis
Inferential analysis goes beyond describing the sample.
It helps researchers evaluate evidence about relationships, differences, or effects.
Common concepts include:
- Hypothesis testing
- P-values
- Confidence intervals
- Effect sizes
- Statistical significance
- Practical significance
What Is a P-Value?
A p-value is a statistical quantity used within hypothesis testing.
It should not be interpreted as:
“The probability that the hypothesis is true.”
Instead, it is interpreted within the framework of the statistical test and its assumptions.
Researchers should also avoid treating a threshold such as 0.05 as a universal boundary between meaningful and meaningless research.
Confidence Intervals
A confidence interval provides information about the uncertainty around an estimate.
For example, instead of reporting only an estimated difference, a researcher can report the estimated difference together with an appropriate confidence interval.
Statistical vs. Practical Significance
A statistically significant result is not automatically practically important.
With a very large sample, a very small difference can produce statistical significance.
Conversely, a potentially meaningful effect may be estimated imprecisely in a small sample.
This is why researchers should consider effect size, uncertainty, study context, and practical meaning alongside p-values.
Quantitative Data Analysis Methods: Which Method Should You Use?
The following framework can help you identify a starting point.
| Research goal | Possible method |
|---|---|
| Summarize one variable | Descriptive statistics |
| Summarize categories | Frequencies and percentages |
| Compare two independent groups | Independent-samples t-test |
| Compare paired observations | Paired-samples t-test |
| Compare three or more groups | ANOVA |
| Examine association between numerical variables | Correlation |
| Model or predict an outcome | Regression |
| Examine categorical associations | Chi-square |
| Analyze suitable ordinal/non-normal data | Appropriate nonparametric test |
This table is a starting framework, not a substitute for statistical judgment.
For example, two variables may appear to be numerical but still require careful consideration of measurement, distribution, study design, and assumptions.
Quantitative Analysis Examples
Practical examples make it easier to understand when different methods are used.
Example 1: Student Survey Data
Suppose a researcher collects 450 university survey responses.
Variables include:
- Age
- Study hours
- Attendance
- GPA
- Satisfaction score
- Department
The first step would be descriptive analysis.
The researcher might calculate:
- Mean age
- Average study hours
- Average GPA
- Satisfaction frequencies
- Standard deviations
The researcher could then explore whether study hours and GPA are associated.
The appropriate statistical method would depend on the precise research question and characteristics of the variables.
This is a practical example of quantitative analysis because numerical observations are being summarized and examined for relationships.
Example 2: Comparing Two Teaching Methods
Suppose researchers divide students into two groups.
- Group A uses Teaching Method A.
- Group B uses Teaching Method B.
After the course, both groups complete the same test.
Research question:
Do average test scores differ between the two groups?
An independent-samples t-test may be appropriate if its assumptions and study design requirements are satisfied.
The researcher should report more than just whether the result is statistically significant. The difference between groups, uncertainty, and effect size should also be considered.
Example 3: Comparing Three Departments
Suppose a university measures student satisfaction in:
- Business
- Engineering
- Social Sciences
The researcher wants to know whether average satisfaction differs across the three groups.
ANOVA may be appropriate for comparing the group means under suitable assumptions.
If the overall test indicates a difference, follow-up comparisons may be needed to determine where the differences occur.
Example 4: Examining Categorical Associations
Suppose researchers collect data on:
- Department
- Satisfaction category
The question is:
Is satisfaction associated with department?
Because both variables are categorical, a chi-square analysis may be appropriate when the relevant assumptions are satisfied.
Example 5: Predicting Exam Performance
Suppose a researcher wants to determine whether:
- Study hours
- Attendance
- Previous GPA
are associated with final exam performance.
A multiple regression model may be useful if the research question, data structure, and assumptions support it.
The researcher can then examine:
- Coefficients
- Direction of associations
- Model fit
- R²
- Uncertainty
- Residuals
The output should be interpreted in the context of the study rather than treated as proof of causation.
Step 9: Visualize Quantitative Data
Statistical tables provide precision, but visualizations can make patterns easier to understand.
Bar Charts
Useful for comparing categories.
Example:
Average satisfaction by department.
Histograms
Useful for examining the distribution of numerical data.
Example:
Distribution of exam scores.
Box Plots
Useful for comparing distributions, spread, and potential outliers between groups.
Scatter Plots
Useful for examining relationships between numerical variables.
Example:
Study hours vs. exam score.
Line Charts
Useful when measurements are collected across time.
Example:
Monthly sales over a two-year period.
The purpose of visualization should be analytical and communicative. A chart should help the reader understand something relevant to the research question.
Step 10: Interpret Quantitative Research Results
Statistical output is not the same thing as a research finding.
Suppose software produces:
r = 0.42, p < 0.05
The researcher still needs to explain:
- What variables were analyzed?
- What does the direction mean?
- How strong is the association?
- What uncertainty surrounds the estimate?
- Is the relationship meaningful in the context of the research?
- Does the research design support causal interpretation?
A good interpretation connects the statistical result back to the original research question.
For example:
“Study time showed a positive association with exam performance in this sample.”
That is more informative than simply stating:
“The correlation was significant.”
Researchers should also distinguish statistical evidence from causal evidence.
Step 11: Report Quantitative Data Analysis in a Research Paper
A quantitative research paper usually explains the analytical process in the methods section and presents the results separately.
Methods Section
Explain:
- Dataset or participants
- Variables
- Measurement procedures
- Data preparation
- Statistical methods
- Statistical software
- Assumption checks
- Significance criteria where applicable
Results Section
Present:
- Descriptive statistics
- Relevant test results
- Tables
- Figures
- Confidence intervals
- Effect sizes where appropriate
- Important statistical estimates
The results section should focus on what the analysis found.
The discussion section can then explain what those findings may mean in relation to previous research, the research question, limitations, and practical implications.
Avoid Reporting Numbers Without Context
Instead of writing:
“The mean was 78.5.”
Explain what 78.5 represents, which group it describes, how variable the observations were, and why the statistic matters.
How to Analyze Quantitative Data With DataLumio
Researchers do not always need to build a statistical workflow from scratch.
DataLumio provides a no-code workflow for structured quantitative datasets, including CSV, XLSX, and XLS files. Its quantitative analysis workflow can produce descriptive statistics, frequency tables, outlier checks, correlation and regression analysis, chi-square and ANOVA outputs, charts, and plain-language explanations depending on the dataset.
The platform is designed for researchers, students, analysts, and teams who need to work with structured numerical data without writing statistical code.
Upload Your Dataset
Start with a structured dataset such as:
- Survey responses
- Research spreadsheets
- Experimental measurements
- Business records
- Academic datasets
DataLumio currently supports CSV, XLSX, and XLS uploads for its quantitative workflow.
Describe Your Research Question
Researchers can provide context about what they want to investigate.
For example:
“Compare satisfaction scores between undergraduate and postgraduate students.”
Or:
“Examine the relationship between study hours and final exam scores.”
Giving the analysis a clear research objective helps keep the workflow connected to the actual research question.
Review the Dataset
Before interpreting results, check:
- Variable names
- Variable types
- Missing values
- Categories
- Numerical columns
- Potential outliers
DataLumio can identify numerical, categorical, and mixed columns, but the researcher should confirm that the variables have been represented correctly.
Run the Quantitative Analysis
Depending on the dataset, the workflow can produce:
- Descriptive statistics
- Frequency tables
- Outlier checks
- Correlation analysis
- Regression analysis
- Chi-square analysis
- ANOVA
- Visualizations
The exact analysis depends on the available variables and dataset structure.
Review the Results
This step should never be skipped.
A statistical report is a starting point for interpretation, not a replacement for research judgment.
Check the results against:
- Original research questions
- Variable definitions
- Study design
- Sample size
- Statistical assumptions
- Unusual observations
- Research methodology
DataLumio itself recommends reviewing and validating findings before using them in research or decisions.
Use the Results in Your Research Workflow
After reviewing the analysis, researchers can use the findings to support:
- Dissertation analysis
- Thesis results
- Survey research
- Research reports
- Presentations
- Exploratory studies
For advanced statistical procedures or highly customized models, specialist statistical environments such as R, Python, or SPSS may still be more appropriate.
The goal should not be to use the most complicated software available. It should be to use a method and tool that match the research question and analytical requirements.
Common Mistakes When Analyzing Quantitative Data
Even technically correct calculations can produce weak research if the analytical process is poorly designed.
Choosing a Statistical Test Before Defining the Research Question
Start with the question, not the software menu.
Ignoring Missing Data
Missing observations can affect sample size, distributions, and statistical estimates.
Automatically Deleting Outliers
An outlier may be a legitimate observation.
Investigate it first.
Ignoring Statistical Assumptions
A test should not be selected simply because it is familiar.
Using the Mean for Every Dataset
The mean may not adequately describe highly skewed distributions.
Treating P-Values as the Whole Result
Statistical significance does not describe the magnitude or practical importance of an effect.
Confusing Correlation With Causation
An association between two variables does not automatically demonstrate that one causes the other.
Running Too Many Tests Without a Clear Plan
Testing many relationships without a coherent analytical strategy can increase the likelihood of misleading findings.
Reporting Software Output Without Interpretation
Readers need to understand what the numbers mean for the research question.
Best Practices for Quantitative Data Analysis
A reliable workflow should include the following:
- Start with a clearly defined research question.
- Identify and document the variables.
- Understand measurement levels.
- Prepare and clean the dataset.
- Investigate missing values.
- Examine distributions and unusual observations.
- Begin with descriptive statistics.
- Select methods based on the research question and data.
- Check relevant assumptions.
- Use appropriate inferential methods.
- Consider effect sizes and confidence intervals.
- Visualize important findings.
- Document analytical decisions.
- Interpret results in their research context.
- Report limitations honestly.
- Preserve enough methodological detail for the analysis to be understood and, where possible, reproduced.
Quantitative analysis is strongest when each stage connects logically to the next.
Quantitative Data Analysis Tools and Software
Researchers can use different tools depending on the complexity of their analysis.
Excel
Useful for:
- Basic data preparation
- Formulas
- Tables
- Simple descriptive statistics
- Charts
SPSS
Widely used for academic and applied statistical analysis, particularly where researchers prefer a graphical interface and need a broad range of statistical procedures.
R
A powerful programming environment for statistical analysis, visualization, modelling, and reproducible research.
Python
Useful for statistical analysis, data manipulation, visualization, automation, and advanced analytical workflows.
Jamovi
Provides a graphical statistical workflow that can be useful for researchers and students who prefer not to write statistical code.
DataLumio
DataLumio provides a no-code workflow for structured quantitative data, with supported spreadsheet uploads and outputs including descriptive statistics, statistical tests, charts, outlier checks, and plain-language explanations.
The best tool depends on the researcher’s technical requirements, statistical methods, study design, and need for customization.
Frequently Asked Questions About Quantitative Data Analysis
What is quantitative data analysis?
Quantitative data analysis is the process of examining numerical data using statistical methods to describe observations, identify patterns, compare groups, examine relationships, test hypotheses, and support research conclusions.
How do you analyze quantitative data?
A typical workflow involves defining the research question, identifying variables, cleaning the dataset, exploring the data, calculating descriptive statistics, selecting appropriate statistical methods, checking assumptions, performing analysis, interpreting results, and reporting findings.
What are the main quantitative data analysis methods?
Common methods include descriptive statistics, t-tests, ANOVA, correlation, regression, chi-square analysis, and appropriate nonparametric methods. The correct method depends on the research question, variables, study design, and assumptions.
What are the types of quantitative analysis?
Common categories include descriptive, inferential, comparative, correlational, predictive, and exploratory analysis.
What are examples of quantitative data?
Examples include age, income, test scores, GPA, survey ratings, attendance percentage, sales revenue, blood pressure, response time, and experimental measurements.
What are examples of quantitative analysis?
Examples include calculating average survey scores, comparing two groups using a t-test, comparing several groups with ANOVA, examining correlations between variables, and using regression to model an outcome.
How do you choose a quantitative analysis method?
Begin with the research question. Then identify the variables, their measurement levels, study design, number of groups, distribution, sample size, and relevant assumptions. Select the statistical method that fits those conditions.
What is the difference between descriptive and inferential analysis?
Descriptive analysis summarizes the data collected. Inferential analysis evaluates evidence about relationships, differences, or effects and can be used to make statistical inferences beyond the observed sample when the study design supports them.
Can quantitative analysis prove causation?
Not by itself. Causal conclusions depend heavily on research design, control of confounding factors, assumptions, and the overall body of evidence. A correlation alone does not prove that one variable caused another.
What software can be used for quantitative data analysis?
Researchers commonly use Excel, SPSS, R, Python, Jamovi, and specialized research-analysis platforms such as DataLumio. The appropriate choice depends on the complexity of the analysis and the researcher’s requirements.
Can students use DataLumio for quantitative research?
Yes. DataLumio is designed to support structured quantitative datasets such as survey responses and research spreadsheets. Students can use it to generate a first-pass analysis and then review the findings against their research methodology.
Final Checklist: How to Analyze Quantitative Data
Before finalizing your quantitative research analysis, ask:
- Did I clearly define the research question?
- Did I identify all relevant variables?
- Did I confirm how the variables are measured?
- Did I clean the dataset?
- Did I investigate missing values?
- Did I check for unusual observations?
- Did I explore the distributions?
- Did I calculate appropriate descriptive statistics?
- Did I select the statistical method based on the research question?
- Did I check the method’s assumptions?
- Did I interpret effect size and uncertainty where appropriate?
- Did I avoid treating correlation as causation?
- Did I use appropriate visualizations?
- Did I explain what the results mean?
- Did I connect the findings back to the research question?
- Did I document important analytical decisions?
- Did I acknowledge limitations?
The complete process can be summarized as:
Research question → Variables → Data cleaning → Exploration → Descriptive statistics → Method selection → Assumption checks → Inferential analysis → Interpretation → Visualization → Reporting
The purpose of quantitative data analysis is not simply to produce more numbers. It is to turn numerical observations into evidence that can answer a well-defined research question.
When the research question, dataset, statistical method, and interpretation all align, quantitative analysis becomes much easier to understand and much more useful for research.